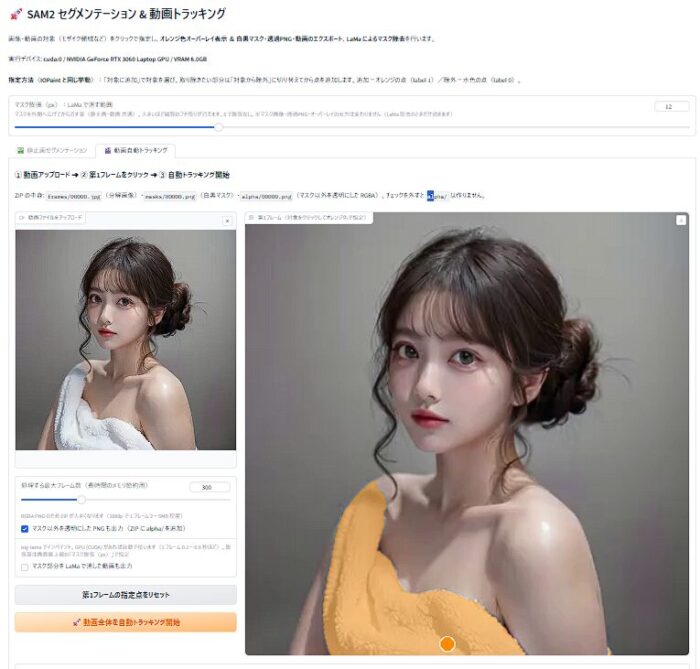
import os
import json
import time
import shutil
import hashlib
import tempfile
import traceback
import zipfile
import subprocess
from concurrent.futures import ThreadPoolExecutor
import cv2
import gradio as gr
import numpy as np
from PIL import Image, ImageDraw
import torch
from omegaconf import OmegaConf
from hydra.utils import instantiate
from sam2.sam2_image_predictor import SAM2ImagePredictor
# パス設定
_SCRIPT_DIR = os.path.dirname(os.path.abspath(__file__))
MODEL_CFG = os.path.join(_SCRIPT_DIR, "sam2.1_hiera_l.yaml")
CHECKPOINT = os.path.join(_SCRIPT_DIR, "checkpoints", "sam2.1_hiera_large.pt")
OUTPUTS_DIR = os.path.join(_SCRIPT_DIR, "outputs")
os.makedirs(OUTPUTS_DIR, exist_ok=True)
# ----------------------------------------------------
# デバイス設定(GPU があれば必ず使う)
# ----------------------------------------------------
device = "cuda" if torch.cuda.is_available() else "cpu"
if device == "cuda":
# 同じサイズの推論が続くので cudnn のベンチマークを使ってカーネルを選ばせる
torch.backends.cudnn.benchmark = True
# Ampere 以降は TF32 で畳み込み・行列積が速くなる(精度差はごく僅か)
torch.backends.cudnn.allow_tf32 = True
torch.backends.cuda.matmul.allow_tf32 = True
try:
torch.cuda.set_device(0)
except Exception:
pass
def device_description():
"""UI・ログ表示用のデバイス説明(例: cuda:0 / NVIDIA GeForce RTX 3060 Laptop GPU / 6.4GB)"""
if device != "cuda":
return "cpu(GPU が検出されませんでした。CUDA 版 PyTorch を入れると高速になります)"
try:
name = torch.cuda.get_device_name(0)
total_gb = torch.cuda.get_device_properties(0).total_memory / (1024 ** 3)
return f"cuda:0 / {name} / VRAM {total_gb:.1f}GB"
except Exception:
return "cuda:0"
print(f"[device] 使用デバイス: {device_description()}")
print(f"[device] torch {torch.__version__}")
# ----------------------------------------------------
# モデル構築(静止画用 & 動画用 Lazy Load)
# ----------------------------------------------------
def build_image_model(cfg_path: str, ckpt_path: str):
cfg = OmegaConf.load(cfg_path)
model = instantiate(cfg.model)
state = torch.load(ckpt_path, map_location="cpu")
sd = state.get("model", state)
model.load_state_dict(sd, strict=False)
model.to(device)
model.eval()
return model
image_model = build_image_model(MODEL_CFG, CHECKPOINT)
image_predictor = SAM2ImagePredictor(image_model)
_video_predictor = None
def get_video_predictor():
global _video_predictor
if _video_predictor is None:
cfg = OmegaConf.load(MODEL_CFG)
cfg.model._target_ = "sam2.sam2_video_predictor.SAM2VideoPredictor"
cfg.model.fill_hole_area = 8
model = instantiate(cfg.model, _recursive_=True)
state = torch.load(CHECKPOINT, map_location="cpu")
sd = state.get("model", state)
model.load_state_dict(sd, strict=False)
model.to(device)
model.eval()
_video_predictor = model
return _video_predictor
# ----------------------------------------------------
# 共通ヘルパー関数
# ----------------------------------------------------
_cached_image = {"md5": None, "np": None}
def ensure_image_set(pil_img):
"""IOPaint と同じく画像の md5 でキャッシュし、同じ画像は set_image しない"""
img_np = np.array(pil_img.convert("RGB"))
img_md5 = hashlib.md5(img_np.tobytes()).hexdigest()
if _cached_image["md5"] != img_md5:
image_predictor.set_image(img_np)
_cached_image["md5"] = img_md5
_cached_image["np"] = img_np
return _cached_image["np"]
# 点の色(Positive = 対象に追加 / Orange, Negative = 対象から除外 / 水色)
POINT_COLORS = {1: (255, 140, 0), 0: (0, 170, 255)}
def _point_label(pt):
"""[x, y] または [x, y, label] から label(1=追加 / 0=除外) を取り出す"""
try:
return 1 if int(pt[2]) else 0
except (IndexError, TypeError, ValueError):
return 1
def _make_cutout_rgba(image_np, bw_mask_np):
"""RGB 画像と白黒マスクから、マスク(白)以外を透明にした RGBA 画像を作る"""
alpha = np.where(bw_mask_np > 0, 255, 0).astype(np.uint8)
if alpha.shape[:2] != image_np.shape[:2]:
alpha = cv2.resize(alpha, (image_np.shape[1], image_np.shape[0]),
interpolation=cv2.INTER_NEAREST)
return Image.fromarray(np.dstack([image_np, alpha])) # RGBA
def draw_points(image, points, radius=6):
if image is None or not points:
return image
img_draw = image.copy().convert("RGB")
draw = ImageDraw.Draw(img_draw)
for pt in points:
if not pt or len(pt) < 2 or pt[0] is None or pt[1] is None:
continue
try:
x, y = int(pt[0]), int(pt[1])
except (ValueError, TypeError):
continue
color = POINT_COLORS[_point_label(pt)]
draw.ellipse([x - radius - 1, y - radius - 1, x + radius + 1, y + radius + 1], fill=(255, 255, 255))
draw.ellipse([x - radius, y - radius, x + radius, y + radius], fill=color)
return img_draw
def _to_coord(x, y, image=None):
"""(x, y) を整数画像座標へ変換する。null / NaN / 変換不能なら None を返す。
image が渡された場合は画像サイズ内にクランプする。"""
if x is None or y is None:
return None
try:
# float('nan') / 'inf' は int() で ValueError / OverflowError になるので弾かれる
ix, iy = int(round(float(x))), int(round(float(y)))
except (TypeError, ValueError, OverflowError):
return None
if image is not None:
try:
w, h = image.size
except (AttributeError, TypeError, ValueError):
return None
ix = max(0, min(w - 1, ix))
iy = max(0, min(h - 1, iy))
return (ix, iy)
def extract_coords(evt: gr.SelectData, image=None):
"""Gradio の SelectData から (x, y) 座標を抽出する
gradio 4.10.0 の標準形式は index=[x, y](リスト)。
フロントエンドの不具合で index=[null, null] が届くケースがあるため、
null / NaN は「座標なし」として扱う。
"""
if evt is None:
return None, "イベントデータが取得できませんでした。画像をもう一度クリックしてください。"
idx = getattr(evt, "index", None)
val = getattr(evt, "value", None)
# 1. 2要素のリスト/タプル(gradio の標準形式)
if isinstance(idx, (list, tuple)) and len(idx) >= 2:
coord = _to_coord(idx[0], idx[1], image)
if coord is not None:
return coord, None
# 2. 辞書型
elif isinstance(idx, dict):
inner = idx.get("index")
x = idx.get("x", idx.get("col"))
y = idx.get("y", idx.get("row"))
if x is None and y is None and isinstance(inner, (list, tuple)) and len(inner) >= 2:
x, y = inner[0], inner[1]
coord = _to_coord(x, y, image)
if coord is not None:
return coord, None
# 3. 単一数値(フラット化インデックス: idx = y * width + x)
elif isinstance(idx, (int, float)) and not isinstance(idx, bool) and image is not None:
try:
w, h = image.size
raw_idx = int(idx)
coord = _to_coord(raw_idx % w, raw_idx // w, image)
if coord is not None:
return coord, None
except (TypeError, ValueError, OverflowError, ZeroDivisionError):
pass
# 4. evt.value からのフォールバック
if isinstance(val, (list, tuple)) and len(val) >= 2:
coord = _to_coord(val[0], val[1], image)
if coord is not None:
return coord, None
return None, (
f"クリック位置の座標を取得できませんでした(受信: index={idx}, value={val})。"
"ブラウザが古い JavaScript をキャッシュしている可能性があります。"
"ページを再読み込み(Ctrl+F5)してから画像の中央付近をクリックするか、"
"『手動座標で指定』から座標を直接入力してください。"
)
# ----------------------------------------------------
# 1. 静止画セグメンテーション & マスク・座標エクスポート
# ----------------------------------------------------
@torch.inference_mode()
def process_segmentation_with_point(image, points, cur_x, cur_y, cur_label=1):
"""(cur_x, cur_y, cur_label) を points に追加してセグメンテーションを実行
IOPaint の InteractiveSeg.forward() と同じ呼び出し方にする:
- multimask_output=False(1 枚だけ採用。_scores の argmax は使わない)
- label=1 で対象に追加 / label=0 で対象から除外
- torch.inference_mode() で実行
"""
valid_points = []
for pt in (points or []):
if isinstance(pt, (list, tuple)) and len(pt) >= 2:
if pt[0] is not None and pt[1] is not None:
try:
valid_points.append([int(pt[0]), int(pt[1]), _point_label(pt)])
except (ValueError, TypeError):
continue
valid_points.append([int(cur_x), int(cur_y), 1 if int(cur_label) else 0])
image_np = ensure_image_set(image)
point_coords = np.array([p[:2] for p in valid_points], dtype=np.float32)
point_labels = np.array([p[2] for p in valid_points], dtype=np.int32)
masks, scores, _ = image_predictor.predict(
point_coords=point_coords,
point_labels=point_labels,
multimask_output=False
)
if isinstance(masks, torch.Tensor):
masks = masks.detach().cpu().numpy()
if isinstance(scores, torch.Tensor):
scores = scores.detach().cpu().numpy()
best_mask = masks[0]
if best_mask.ndim == 3 and best_mask.shape[0] == 1:
best_mask = best_mask.squeeze(0)
bool_mask = (best_mask > 0.0)
# 1. オレンジ色オーバーレイ画像
overlay = image_np.copy()
orange_color = np.array([255, 140, 0], dtype=np.float32)
alpha = 0.5
if bool_mask.any():
target_pixels = overlay[bool_mask].astype(np.float32)
blended = target_pixels * (1.0 - alpha) + orange_color * alpha
overlay[bool_mask] = np.clip(blended, 0, 255).astype(np.uint8)
result_img = Image.fromarray(overlay)
result_img = draw_points(result_img, valid_points)
# 2. 白黒マスク画像 (0 or 255)
bw_mask_np = (bool_mask.astype(np.uint8) * 255)
bw_mask_img = Image.fromarray(bw_mask_np)
# 3. マスク以外を透明にした RGBA 画像(元画像ベース。オレンジ合成や点は入れない)
cutout_img = _make_cutout_rgba(image_np, bw_mask_np)
# 4. エクスポート用ファイル自動生成
timestamp = time.strftime("%Y%m%d_%H%M%S")
mask_path = os.path.join(OUTPUTS_DIR, f"mask_{timestamp}.png")
bw_mask_img.save(mask_path)
cutout_path = os.path.join(OUTPUTS_DIR, f"cutout_{timestamp}.png")
cutout_img.save(cutout_path)
json_path = os.path.join(OUTPUTS_DIR, f"points_{timestamp}.json")
with open(json_path, "w", encoding="utf-8") as f:
json.dump({
"timestamp": timestamp,
"points": valid_points,
"point_labels": point_labels.tolist(),
"image_size": [image_np.shape[1], image_np.shape[0]]
}, f, indent=2)
n_pos = int(sum(p[2] for p in valid_points))
n_neg = len(valid_points) - n_pos
status_text = (
f"完了: 追加 {n_pos} / 除外 {n_neg} "
f"(X={cur_x}, Y={cur_y}, {'追加' if int(cur_label) else '除外'}) | "
f"画像サイズ {image_np.shape[1]}x{image_np.shape[0]} | "
f"保存済: {os.path.basename(mask_path)} / {os.path.basename(cutout_path)}"
)
return (valid_points, result_img, bw_mask_img, cutout_img,
mask_path, json_path, status_text)
def on_image_select(image, points, evt: gr.SelectData, cur_label=1):
try:
if image is None:
return points or [], None, None, None, None, None, "画像をアップロードしてください"
coord, err_msg = extract_coords(evt, image)
if coord is None:
return points or [], None, None, None, None, None, err_msg
return process_segmentation_with_point(image, points, coord[0], coord[1], cur_label)
except Exception as e:
traceback.print_exc()
return points or [], None, None, None, None, None, f"エラー: {e}"
def on_image_manual_point(image, points, cur_x, cur_y, cur_label=1):
"""クリックを使わず、手動で入力した座標でセグメンテーションを実行する"""
try:
if image is None:
return points or [], None, None, None, None, None, "画像をアップロードしてください"
coord = _to_coord(cur_x, cur_y, image)
if coord is None:
return points or [], None, None, None, None, None, "X と Y に数値を入力してください"
return process_segmentation_with_point(image, points, coord[0], coord[1], cur_label)
except Exception as e:
traceback.print_exc()
return points or [], None, None, None, None, None, f"エラー: {e}"
def on_image_reset(image=None):
if image is None:
return [], None, None, None, None, None, "画像をアップロードしてください"
w, h = image.size
return [], None, None, None, None, None, (
f"画像サイズ: {w} x {h} px。対象をクリックしてください"
"(クリックが反応しない場合は『手動座標で指定』から X / Y を入力)"
)
# ----------------------------------------------------
# 1.5 マスク部分を消す(LaMa インペイント)
# advimman/lama の big-lama(TorchScript)を checkpoints/big-lama.pt から遅延ロードする
# ----------------------------------------------------
LAMA_CHECKPOINT = os.path.join(_SCRIPT_DIR, "checkpoints", "big-lama.pt")
_LAMA_MAX_SIDE = 1280 # 推論時の最大辺(これを超える領域は縮小して処理し、後で戻す)
# UI の「マスク膨張(px)」初期値。従来の自動値(長辺×0.4% で 2〜10px / 1080p なら 8px)より
# 少し大きめにして、輪郭のフチ残りが出にくいようにしている。
DEFAULT_DILATE_PX = 12
DILATE_MAX_PX = 40 # UI スライダーの上限
_lama_model = None
_lama_device = None # LaMa が実際に動くデバイス(GPU が使えなければ "cpu" に落ちる)
def _lama_probe(model, dev):
"""64x64 のダミー推論で、そのデバイス上で本当に動くか確認する
GPU を選んでおきながら実際にはメモリ不足などで落ちる、という事態を防ぐ。
"""
if dev == "cpu":
return
img_t = torch.zeros(1, 3, 64, 64, device=dev)
msk_t = torch.zeros(1, 1, 64, 64, device=dev)
msk_t[..., 16:48, 16:48] = 1.0
with torch.inference_mode():
out = model(img_t, msk_t)
if dev == "cuda":
torch.cuda.synchronize()
if tuple(out.shape[-2:]) != (64, 64):
raise RuntimeError(f"LaMa の出力サイズが不正です: {tuple(out.shape)}")
if not torch.isfinite(out).all():
raise RuntimeError("LaMa の出力に NaN / Inf が含まれています")
def get_lama_model():
"""LaMa(TorchScript)を 1 回だけ読み込む(GPU 優先・失敗したら CPU に自動フォールバック)"""
global _lama_model, _lama_device
if _lama_model is None:
if not os.path.exists(LAMA_CHECKPOINT):
raise FileNotFoundError(
f"LaMa のモデルが見つかりません: {LAMA_CHECKPOINT}"
)
print(f"[lama] モデルを読み込み中: {os.path.basename(LAMA_CHECKPOINT)}")
candidates = ["cuda", "cpu"] if device == "cuda" else ["cpu"]
last_err = None
for dev in candidates:
try:
model = torch.jit.load(LAMA_CHECKPOINT, map_location=dev)
model.eval()
_lama_probe(model, dev) # 実際に推論できるか確認
except Exception as e:
last_err = e
print(f"[lama] {dev} では実行できません: {type(e).__name__}: {e}")
model = None
if dev != "cpu":
print("[lama] CPU で再試行します(処理は遅くなります)")
try:
torch.cuda.empty_cache()
except Exception:
pass
continue
_lama_model, _lama_device = model, dev
print(f"[lama] 読み込み完了({dev})")
break
if _lama_model is None:
raise RuntimeError(
f"LaMa を読み込めませんでした: {type(last_err).__name__}: {last_err}"
)
return _lama_model
def lama_device_name():
"""LaMa が実際に使っているデバイス名(未ロード時は想定デバイス)"""
return _lama_device or device
def auto_dilate_px(shape_hw):
"""画像サイズに応じたマスク膨張量の自動値(長辺×0.4% を 2〜10px)"""
h, w = shape_hw[0], shape_hw[1]
return max(2, min(10, int(round(0.004 * max(h, w)))))
@torch.inference_mode()
def lama_inpaint_rgb(image_rgb, mask_u8, max_side=_LAMA_MAX_SIDE, dilate_px=None):
"""LaMa でマスク(>0)の部分を消す。マスク以外の画素は元画像のまま返す
image_rgb : (H, W, 3) uint8 の RGB 画像
mask_u8 : (H, W) uint8 のマスク(0=残す / >0=消す)
dilate_px : 消す前にマスクを膨張させる量(px)。0 で膨張なし。
None のときは画像サイズに応じた自動値(長辺×0.4% を 2〜10px)
戻り値 : (H, W, 3) uint8 の RGB 画像
マスクの境界は色(輪郭のフチ)が残って LaMa が対象色を内側へ塗り広げてしまうため、
膨張させてから消す(そのため「マスクのすぐ外側の数px」も塗り直される)。
"""
img = np.ascontiguousarray(image_rgb, dtype=np.uint8)
msk = np.ascontiguousarray(mask_u8, dtype=np.uint8)
if msk.shape[:2] != img.shape[:2]:
msk = cv2.resize(msk, (img.shape[1], img.shape[0]), interpolation=cv2.INTER_NEAREST)
binm = msk > 0
if not binm.any():
return img.copy()
# SAM2 のマスクは対象にぴったり沿うため、境界の色が残って
# LaMa が対象色を内側へ塗り広げてしまう。指定量だけ膨張させてから消す。
if dilate_px is None:
dilate_px = auto_dilate_px(img.shape[:2])
dilate_px = int(max(0, min(200, round(float(dilate_px)))))
if dilate_px > 0:
kernel = cv2.getStructuringElement(
cv2.MORPH_ELLIPSE, (2 * dilate_px + 1, 2 * dilate_px + 1)
)
msk = cv2.dilate(msk, kernel)
# マスクのバウンディングボックス+余白だけを処理する(全面より大幅に速い)
ys, xs = np.where(binm)
y0, y1 = int(ys.min()), int(ys.max()) + 1
x0, x1 = int(xs.min()), int(xs.max()) + 1
pad = max(32, int(0.25 * max(y1 - y0, x1 - x0)))
y0, y1 = max(0, y0 - pad), min(img.shape[0], y1 + pad)
x0, x1 = max(0, x0 - pad), min(img.shape[1], x1 + pad)
crop_img = img[y0:y1, x0:x1]
crop_msk = msk[y0:y1, x0:x1]
ch, cw = crop_img.shape[:2]
# 大きすぎる場合は縮小して推論(メモリ・速度対策)
scale = min(1.0, float(max_side) / max(ch, cw))
if scale < 1.0:
nw = max(8, int(round(cw * scale)))
nh = max(8, int(round(ch * scale)))
work_img = cv2.resize(crop_img, (nw, nh), interpolation=cv2.INTER_AREA)
work_msk = cv2.resize(crop_msk, (nw, nh), interpolation=cv2.INTER_NEAREST)
else:
work_img, work_msk = crop_img, crop_msk
# 小さすぎる領域はモデルが扱えない(内部で 1x1 まで縮む)ので、最低 64px に拡大する
min_side = min(work_img.shape[:2])
if min_side < 64:
s = 64.0 / float(min_side)
nw = max(8, int(round(work_img.shape[1] * s)))
nh = max(8, int(round(work_img.shape[0] * s)))
work_img = cv2.resize(work_img, (nw, nh), interpolation=cv2.INTER_CUBIC)
work_msk = cv2.resize(work_msk, (nw, nh), interpolation=cv2.INTER_NEAREST)
# LaMa(FFC)は縦横が 8 の倍数である必要があるので reflect パディングする
wh, ww = work_img.shape[:2]
pad_h, pad_w = (8 - wh % 8) % 8, (8 - ww % 8) % 8
img_t = torch.from_numpy(work_img).permute(2, 0, 1).float().div_(255.0)[None]
msk_t = torch.from_numpy((work_msk > 0).astype(np.float32))[None, None]
if pad_h or pad_w:
# reflect は「パディング量 < 元サイズ」の制約があるので、小さい画像では replicate に落とす
mode = "reflect" if (pad_h < wh and pad_w < ww) else "replicate"
img_t = torch.nn.functional.pad(img_t, (0, pad_w, 0, pad_h), mode=mode)
msk_t = torch.nn.functional.pad(msk_t, (0, pad_w, 0, pad_h))
model = get_lama_model() # 実際に推論できるデバイスを確定させる
dev = _lama_device or device
img_t = img_t.to(dev)
msk_t = msk_t.to(dev)
out = model(img_t, msk_t)
out = out[..., :wh, :ww] # パディングを戻す
if float(out.max()) > 1.5: # 0-255 版の重みにも対応
out = out / 255.0
out = out.clamp_(0, 1)[0].permute(1, 2, 0).float().cpu().numpy()
out_u8 = np.clip(out * 255.0 + 0.5, 0, 255).astype(np.uint8)
if (wh, ww) != (ch, cw):
out_u8 = cv2.resize(out_u8, (cw, ch), interpolation=cv2.INTER_LINEAR)
# マスク外は元の画素をそのまま使う(境界のわずかな色ずれを防ぐ)
result = img.copy()
region = result[y0:y1, x0:x1]
inside = crop_msk > 0
region[inside] = out_u8[inside]
return result
def on_image_erase(image, mask_img, dilate_px=DEFAULT_DILATE_PX):
"""静止画: 白黒マスクの部分を LaMa で消す
dilate_px : 消す前にマスクを膨張させる量(px)。0 で膨張なし
"""
try:
if image is None:
return None, "画像をアップロードしてください"
if mask_img is None:
return None, "先に対象をクリックしてマスクを作成してください"
image_np = np.array(image.convert("RGB"))
mask_np = np.array(mask_img.convert("L"))
if mask_np.max() == 0:
return None, "マスクが空です。対象をクリックしてから実行してください"
t0 = time.time()
# 膨張量を確定(None は画像サイズに応じた自動値)
if dilate_px is None:
dilate_px = auto_dilate_px(image_np.shape[:2])
dilate_px = int(max(0, min(200, round(float(dilate_px)))))
erased_np = lama_inpaint_rgb(image_np, mask_np, dilate_px=dilate_px)
erased_img = Image.fromarray(erased_np)
timestamp = time.strftime("%Y%m%d_%H%M%S")
erased_path = os.path.join(OUTPUTS_DIR, f"erased_{timestamp}.png")
erased_img.save(erased_path)
return erased_img, (
f"LaMa でマスク部分を消しました(マスク膨張 {dilate_px}px / "
f"{time.time() - t0:.1f} 秒 / {lama_device_name()})| "
f"保存済: {os.path.basename(erased_path)}"
)
except Exception as e:
traceback.print_exc()
try:
_log_exception("静止画 LaMa インペイント", e)
except Exception:
pass
return None, f"消去に失敗しました: {type(e).__name__}: {e}"
# ----------------------------------------------------
# 2. 動画トラッキング処理
# ----------------------------------------------------
_video_state = {
"temp_dir": None,
"fps": 30,
"width": 0,
"height": 0,
"total_frames": 0,
"first_frame_pil": None,
}
def on_video_upload(video_path, max_frames):
"""動画がアップロードされたら、フレームを一時展開して第1フレームを表示
※ 戻り値は 9 個(image / state / video / video / video(LaMa) / file(mask mp4) / file(LaMa mp4) / file(zip) / textbox)
"""
if video_path is None:
return None, [], None, None, None, None, None, None, "動画ファイルをアップロードしてください"
try:
# 既存の一時フォルダがあればクリーンアップ
if _video_state["temp_dir"] and os.path.exists(_video_state["temp_dir"]):
shutil.rmtree(_video_state["temp_dir"], ignore_errors=True)
temp_dir = tempfile.mkdtemp(prefix="sam2_video_")
_video_state["temp_dir"] = temp_dir
cap = cv2.VideoCapture(video_path)
if not cap.isOpened():
return None, [], None, None, None, None, None, None, "動画ファイルを開けませんでした"
fps = cap.get(cv2.CAP_PROP_FPS) or 30.0
width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH))
height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT))
total = int(cap.get(cv2.CAP_PROP_FRAME_COUNT))
_video_state["fps"] = fps
_video_state["width"] = width
_video_state["height"] = height
frame_idx = 0
first_frame = None
limit = min(int(max_frames), total) if max_frames else total
# 読み込みは.VideoCapture をスレッド跨ぎできないので順次、
# JPEG エンコード(cv2.imwrite は GIL を解放する)だけ並列化する
jpg_pool = ThreadPoolExecutor(max_workers=8)
try:
while True:
ret, frame = cap.read()
if not ret or frame_idx >= limit:
break
frame_filename = os.path.join(temp_dir, f"{frame_idx:05d}.jpg")
jpg_pool.submit(cv2.imwrite, frame_filename, frame)
if frame_idx == 0:
first_frame = cv2.cvtColor(frame, cv2.COLOR_BGR2RGB)
frame_idx += 1
finally:
cap.release()
jpg_pool.shutdown(wait=True)
_video_state["total_frames"] = frame_idx
if first_frame is None:
return None, [], None, None, None, None, None, None, "フレームの読み込みに失敗しました"
first_pil = Image.fromarray(first_frame)
_video_state["first_frame_pil"] = first_pil
msg = f"動画展開完了: {frame_idx} フレーム ({width}x{height}, {fps:.1f} fps) | 第1フレームの対象をクリックしてください"
return first_pil, [], None, None, None, None, None, None, msg
except Exception as e:
traceback.print_exc()
return None, [], None, None, None, None, None, None, f"動画展開エラー: {e}"
# -------------------------------------------------
# 動画書き出し(Gradio のプレビューで再生できる mp4 にする)
# mp4v(MPEG-4 Part 2)は Chrome/Edge/Firefox で再生できないため
# avc1(H.264 / Baseline / yuv420p)を優先し、書けなければ mp4v にフォールバックする。
# -------------------------------------------------
_BROWSER_CODECS = ["avc1", "mp4v"]
_WORKING_FOURCC = None # 一度成功した FourCC を覚える(2 本目以降の codec 探索 ~1.7 秒を省く)
_USE_GPU = bool(torch.cuda.is_available())
_OVERLAY_ALPHA = 0.5
_VIDEO_BACKEND = None # "ffmpeg" か "opencv" か(起動後 1 回だけ判定)
_SILENCED_STDERR = None
_GPU_BLEND_ENABLED = None # GPU 合成が使えるか(CUDA メモリ不足で False に落とす)
ERROR_LOG_PATH = os.path.join(_SCRIPT_DIR, "error_log.txt")
def _log_exception(stage, exc):
"""エラー内容をコンソールと error_log.txt に残す(Starlette に潰される前に)"""
try:
detail = "".join(traceback.format_exception(type(exc), exc, exc.__traceback__))
except Exception:
detail = f"{type(exc).__name__}: {exc}"
print(f" {stage} でエラー: {type(exc).__name__}: {exc}")
try:
with open(ERROR_LOG_PATH, "a", encoding="utf-8") as f:
f.write(f"\n===== {time.strftime('%Y-%m-%d %H:%M:%S')} / {stage} =====\n")
f.write(detail)
except OSError:
pass
def _blend_overlay_gpu(frame_bgr, mask_bool_gpu):
"""オレンジ合成を GPU で行う(mask は SAM2 から GPU 上のまま受け取るので CPU 往復を 1 回減らせる)
frame_bgr : (H, W, 3) uint8 の BGR フレーム(CPU)
mask_bool_gpu : (H, W) bool の torch.Tensor(GPU)
戻り値 : 合成後の (H, W, 3) uint8 ndarray(CPU。H.264 エンコード用)
"""
global _GPU_BLEND_ENABLED
device = mask_bool_gpu.device
frame = torch.from_numpy(np.ascontiguousarray(frame_bgr)).to(device, non_blocking=True)
m = mask_bool_gpu.reshape(*mask_bool_gpu.shape[-2:], 1)
orange = torch.tensor([0.0, 140.0, 255.0], device=device).view(1, 1, 3) # BGR
f = frame.to(torch.float32)
blended = f * (1.0 - _OVERLAY_ALPHA) + orange * _OVERLAY_ALPHA
out = torch.where(m, blended, f)
return out.clamp_(0, 255).to(torch.uint8).cpu().numpy()
def _blend_overlay_cpu(frame_bgr, mask_bool):
"""GPU が使えないときの CPU 合成(numpy)"""
overlay_bgr = frame_bgr.copy()
if mask_bool.any():
orange_bgr = np.array([0, 140, 255], dtype=np.float32) # BGR
target_pixels = overlay_bgr[mask_bool].astype(np.float32)
blended = target_pixels * (1.0 - _OVERLAY_ALPHA) + orange_bgr * _OVERLAY_ALPHA
overlay_bgr[mask_bool] = np.clip(blended, 0, 255).astype(np.uint8)
return overlay_bgr
def _disable_gpu_blend(reason_exc):
"""GPU 合成を無効化して CPU に落とす(VRAM 6GB では大容量動画だと OOM しうるため)"""
global _GPU_BLEND_ENABLED
_GPU_BLEND_ENABLED = False
print(" GPU メモリ不足のため、以降の合成は CPU で行います")
print(" (「処理する最大フレーム数」を小さくすると解消します)")
_log_exception("オーバーレイ合成(GPU → CPU に切替)", reason_exc)
try:
torch.cuda.empty_cache()
except Exception:
pass
def _blend_overlay(frame_bgr, mask_bool_gpu, bw_mask):
"""サイズも CUDA も問題ないように GPU / CPU を使い分ける合成
CUDA メモリ不足(OOM)が起きた場合は GPU 合成を無効化して CPU に恒久フォールバックする。
"""
global _GPU_BLEND_ENABLED
if _GPU_BLEND_ENABLED is None:
_GPU_BLEND_ENABLED = _USE_GPU
same_size = tuple(bw_mask.shape) == tuple(mask_bool_gpu.shape[-2:])
if _GPU_BLEND_ENABLED and _USE_GPU and same_size:
try:
return _blend_overlay_gpu(frame_bgr, mask_bool_gpu)
except Exception as e:
oom = isinstance(e, getattr(torch.cuda, "OutOfMemoryError", ())) \
or "out of memory" in str(e).lower()
if not oom:
raise
_disable_gpu_blend(e)
return _blend_overlay_cpu(frame_bgr, bw_mask > 0)
def _even_dim(n):
"""H.264 は縦横が偶数でないと書けないので偶数に合わせる"""
n = int(n)
n -= (n % 2)
return max(2, n)
def _silence_stderr():
"""OpenCV の codec 探知ログ(libopenh264 -load 失敗など)を一時的に標準エラー出力から外す"""
global _SILENCED_STDERR
return _StdErrSilencer()
class _StdErrSilencer:
"""fd 2 を一時的に devnull に向ける(cv2 の C レベル出力は sys.stderr じゃ消せないため)"""
def __enter__(self):
global _SILENCED_STDERR
self._saved = None
if _SILENCED_STDERR is None: # 入れ子の同時実行を避ける
try:
import os as _os
self._saved = _os.dup(2)
devnull = _os.open(_os.devnull, _os.O_WRONLY)
_os.dup2(devnull, 2)
_os.close(devnull)
_SILENCED_STDERR = self
except Exception:
self._saved = None
return self
def __exit__(self, *exc):
global _SILENCED_STDERR
if self._saved is not None:
try:
import os as _os
_os.dup2(self._saved, 2)
_os.close(self._saved)
except Exception:
pass
_SILENCED_STDERR = None
return False
class _FfmpegVideoWriter:
"""ffmpeg プロセスへ BGR24 の raw frame を流し込む(cv2.VideoWriter 互換の最小インターフェース)"""
def __init__(self, proc, log_path):
self._proc = proc
self._log_path = log_path
self._closed = False
self._failed = False
self._broken = False # パイプが壊れた(release は必ず行う必要がある)
def write(self, frame_bgr):
if self._closed or self._broken:
return
try:
self._proc.stdin.write(np.ascontiguousarray(frame_bgr).tobytes())
except (BrokenPipeError, OSError, ValueError) as e:
print(f" ffmpeg へのフレーム書き込みに失敗しました: {e}")
self._failed = True
# _closed は立てない。release() で stdin を閉じて子プロセスを回収しないと
# ffmpeg が stdin 待ちのまま残り、プロセス終了時にハングする。
self._broken = True
def isOpened(self):
return not self._failed and not self._closed
def release(self):
if not self._closed:
self._closed = True
try:
self._proc.stdin.close()
except (OSError, ValueError):
pass
rc = self._proc.wait()
if rc != 0:
self._failed = True
self._log(f"ffmpeg が異常終了しました (rc={rc})")
self._log("") # ログを消す(異常時は中身を出力)
try:
if self._proc.stderr:
self._proc.stderr.close()
except Exception:
pass
def _log(self, message):
try:
with open(self._log_path, "r", encoding="utf-8", errors="replace") as f:
msg = f.read().strip()
except OSError:
msg = ""
if msg:
print(f" {message}: {msg[:300]}")
try:
os.remove(self._log_path)
except OSError:
pass
def _open_ffmpeg_writer(path, fps, size, crf=20):
"""ffmpeg で H.264(baseline / yuv420p / faststart)を書き出す。失敗したら None"""
ffmpeg = _ffmpeg_exe()
if not ffmpeg:
return None
w, h = int(size[0]), int(size[1])
log_path = path + ".ffmpeg.log"
cmd = [
ffmpeg, "-y", "-loglevel", "error",
"-f", "rawvideo", "-pix_fmt", "bgr24",
"-s", f"{w}x{h}", "-framerate", f"{fps:.6f}", "-i", "pipe:0",
"-an",
"-c:v", "libx264", "-preset", "veryfast", "-crf", str(crf),
"-profile:v", "baseline", "-level", "3.1",
"-pix_fmt", "yuv420p", "-movflags", "+faststart",
path,
]
try:
err_fp = open(log_path, "wb")
except OSError:
return None
try:
proc = subprocess.Popen(
cmd, stdin=subprocess.PIPE, stdout=subprocess.DEVNULL, stderr=err_fp
)
except Exception as e:
try:
err_fp.close()
os.remove(log_path)
except OSError:
pass
print(f" ffmpeg を起動できませんでした(OpenCV にフォールバックします): {e}")
return None
err_fp.close() # 子プロセスが継承した FD はそのまま
writer = _FfmpegVideoWriter(proc, log_path)
if writer.isOpened():
return writer
return None
def _pick_video_backend():
"""ffmpeg が使えるか 1 回だけ判定する(OpenCV より高速・ログが静か・画質を明示指定できる)"""
global _VIDEO_BACKEND
if _VIDEO_BACKEND is not None:
return _VIDEO_BACKEND
probe_path = os.path.join(tempfile.gettempdir(), "sam2_video_encoder_probe.mp4")
probe = _open_ffmpeg_writer(probe_path, 10.0, (32, 32), crf=30)
ok = False
if probe is not None:
for _ in range(3):
probe.write(np.zeros((32, 32, 3), dtype=np.uint8))
probe.release()
ok = os.path.exists(probe_path) and os.path.getsize(probe_path) > 0
try:
os.remove(probe_path)
except OSError:
pass
_VIDEO_BACKEND = "ffmpeg" if ok else "opencv"
if ok:
print(" エンコーダ: ffmpeg (libx264 baseline / yuv420p)")
else:
print(" エンコーダ: OpenCV VideoWriter(avc1)")
return _VIDEO_BACKEND
def _create_video_writer(path, fps, size, crf=20):
"""動画書き出し用の writer を作る。backend が判れば (writer, backend名) を返す"""
if _pick_video_backend() == "ffmpeg":
writer = _open_ffmpeg_writer(path, fps, size, crf=crf)
if writer is not None:
return writer, "ffmpeg"
global _VIDEO_BACKEND
_VIDEO_BACKEND = "opencv" # 実行時に失敗したので以降は OpenCV に切替える
global _WORKING_FOURCC
order = list(_BROWSER_CODECS)
if _WORKING_FOURCC in order: # 前回成功した FourCC を最優先(探索コストを省略)
order.remove(_WORKING_FOURCC)
order.insert(0, _WORKING_FOURCC)
for cc in order:
with _silence_stderr(): # libopenh264 の load 失敗ログ suppress
writer = cv2.VideoWriter(path, cv2.VideoWriter_fourcc(*cc), fps, size)
if writer.isOpened():
_WORKING_FOURCC = cc
return writer, f"OpenCV({cc})"
writer.release()
return None, None
def _ffmpeg_exe():
"""faststart 付きに mux し直すための ffmpeg(無ければ None)"""
exe = shutil.which("ffmpeg")
if exe:
return exe
try:
import imageio_ffmpeg
return imageio_ffmpeg.get_ffmpeg_exe()
except Exception:
return None
def _remux_faststart(path):
"""moov を先頭に置いて、ブラウザがDL完了を待たずに再生できるようにする(ベストエフォート)"""
ffmpeg = _ffmpeg_exe()
if not ffmpeg or not os.path.exists(path):
return False
tmp_path = path + "_faststart.mp4"
try:
result = subprocess.run(
[ffmpeg, "-y", "-loglevel", "error", "-i", path,
"-c", "copy", "-movflags", "+faststart", tmp_path],
stdout=subprocess.PIPE, stderr=subprocess.PIPE, timeout=300,
)
if result.returncode == 0 and os.path.exists(tmp_path) and os.path.getsize(tmp_path) > 0:
shutil.move(tmp_path, path)
return True
except Exception as e:
print(f" faststart 化はスキップします: {e}")
if os.path.exists(tmp_path):
try:
os.remove(tmp_path)
except OSError:
pass
return False
def _fill_missing_frames(temp_dir, temp_masks_dir, temp_frames_dir, total_frames, size,
resize_frames=False, temp_alpha_dir=None):
"""追跡されなかったフレームを補完する(ZIP 内でマスクと画像のファイル名を揃えるため)
- 分解画像(temp_dir/NNNNN.jpg)が ZIP 用ディレクトリに無ければコピーする(再エンコードなし)
- 対応するマスクが無ければ、全黒(0)のマスクを NNNNN.png として作る
- temp_alpha_dir が指定されていれば、マスク以外を透明にした RGBA の NNNNN.png も作る
size: (height, width) マスクの大きさ(動画ライターに合わせて偶数化済み)
resize_frames: True ならマスクと同じサイズへリサイズして書き出す(動画が奇数サイズのとき)
戻り値: (追加したフレーム数, 追加した黒マスク数, 追加した透過PNG数)
"""
height, width = int(size[0]), int(size[1])
black = None
added_frames = 0
added_masks = 0
added_alphas = 0
for i in range(int(total_frames)):
frame_src = os.path.join(temp_dir, f"{i:05d}.jpg")
if not os.path.exists(frame_src):
continue # 展開されていないフレームはスキップ
frame_dst = os.path.join(temp_frames_dir, f"{i:05d}.jpg")
if not os.path.exists(frame_dst):
try:
if resize_frames:
img = cv2.imread(frame_src)
if img is None:
continue
if img.shape[1] != width or img.shape[0] != height:
img = cv2.resize(img, (width, height), interpolation=cv2.INTER_AREA)
if not cv2.imwrite(frame_dst, img, [cv2.IMWRITE_JPEG_QUALITY, 95]):
continue
else:
shutil.copyfile(frame_src, frame_dst)
added_frames += 1
except OSError as e:
print(f" フレーム {i} のコピーに失敗しました: {e}")
continue
mask_dst = os.path.join(temp_masks_dir, f"{i:05d}.png")
if not os.path.exists(mask_dst):
if black is None:
black = np.zeros((height, width), dtype=np.uint8)
if cv2.imwrite(mask_dst, black):
added_masks += 1
# マスク以外を透明にした RGBA(黒マスクなら全透明になる)
if temp_alpha_dir:
alpha_dst = os.path.join(temp_alpha_dir, f"{i:05d}.png")
if not os.path.exists(alpha_dst):
img = cv2.imread(frame_dst, cv2.IMREAD_COLOR)
msk = cv2.imread(mask_dst, cv2.IMREAD_GRAYSCALE)
if img is not None and msk is not None:
if msk.shape[:2] != img.shape[:2]:
msk = cv2.resize(msk, (img.shape[1], img.shape[0]),
interpolation=cv2.INTER_NEAREST)
rgba = np.dstack([img, msk]) # B,G,R,A(cv2 は BGRA 順で書き出す)
if cv2.imwrite(alpha_dst, rgba, [cv2.IMWRITE_PNG_COMPRESSION, 1]):
added_alphas += 1
return added_frames, added_masks, added_alphas
@torch.inference_mode()
def on_first_frame_click(points, evt: gr.SelectData, cur_label=1):
"""動画の第1フレームをクリックして対象を指定(IOPaint と同じ方式)"""
first_pil = _video_state["first_frame_pil"]
if first_pil is None:
return points or [], None, "第1フレームが読み込まれていません"
coord, err_msg = extract_coords(evt, first_pil)
if coord is None:
return points or [], first_pil, err_msg
x, y = coord
new_points = (points or []) + [[x, y, 1 if int(cur_label) else 0]]
# 1フレーム目でのSAM2プレビュー
try:
image_np = ensure_image_set(first_pil)
point_coords = np.array([p[:2] for p in new_points], dtype=np.float32)
point_labels = np.array([_point_label(p) for p in new_points], dtype=np.int32)
masks, scores, _ = image_predictor.predict(
point_coords=point_coords,
point_labels=point_labels,
multimask_output=False
)
if isinstance(masks, torch.Tensor):
masks = masks.detach().cpu().numpy()
if isinstance(scores, torch.Tensor):
scores = scores.detach().cpu().numpy()
best_mask = masks[0]
if best_mask.ndim == 3 and best_mask.shape[0] == 1:
best_mask = best_mask.squeeze(0)
bool_mask = (best_mask > 0.0)
overlay = image_np.copy()
orange_color = np.array([255, 140, 0], dtype=np.float32)
alpha = 0.5
if bool_mask.any():
target_pixels = overlay[bool_mask].astype(np.float32)
blended = target_pixels * (1.0 - alpha) + orange_color * alpha
overlay[bool_mask] = np.clip(blended, 0, 255).astype(np.uint8)
result_img = Image.fromarray(overlay)
result_img = draw_points(result_img, new_points)
n_pos = int(sum(_point_label(p) for p in new_points))
n_neg = len(new_points) - n_pos
return new_points, result_img, (
f"追加 {n_pos} / 除外 {n_neg} 指定中。"
"「動画全体を自動トラッキング」を押してください。"
)
except Exception as e:
img_marked = draw_points(first_pil, new_points)
return new_points, img_marked, f"プレビュー生成に失敗しました: {e}"
def run_video_tracking(points, transparent_png=True, erase_masked=False,
dilate_px=DEFAULT_DILATE_PX,
progress=gr.Progress(track_tqdm=True)):
"""第1フレームの指定点をもとに、SAM2で動画全フレームを自動追跡&エクスポート
transparent_png=True のときは、マスク以外を透明にした RGBA PNG も ZIP の alpha/ に入れる。
erase_masked=True のときは、マスク部分を LaMa で消した動画も書き出す。
dilate_px は LaMa で消す前のマスク膨張量(px)。0 で膨張なし。
※ Gradio の進捗送信は「レスポンス開始後」になるため、ここで例外を投げると
Starlette が "Caught handled exception, but response already started" に化けて
本当の原因が消える。例外は全て _log_exception で記録し、ステータスとして返す。
"""
temp_dir = _video_state["temp_dir"]
total_frames = _video_state["total_frames"]
# 戻り値は 7 個(overlay / mask動画 / mask動画DL / ZIP / 消去動画 / 消去動画DL / status)
def _fail(msg):
return None, None, None, None, None, None, msg
if not temp_dir or total_frames == 0:
return _fail("先に動画をアップロードしてください")
if not points or len(points) == 0:
return _fail("第1フレームに対象をクリックして指定してください")
# 途中で return / 例外が出ても ffmpeg 子プロセスと作業用ディレクトリを必ず片付ける
active_writers = []
temp_masks_dir = None
temp_frames_dir = None # ZIP に入れる元フレーム画像(マスクと同じ連番)
temp_alpha_dir = None # マスク以外を透明にした RGBA PNG(チェックON時のみ)
out_erased_path = None # LaMa でマスクを消した動画(チェックON時のみ)
try:
progress(0.1, desc="SAM2 動画トラッキングモデルの初期化...")
v_predictor = get_video_predictor()
inference_state = v_predictor.init_state(video_path=temp_dir)
v_predictor.reset_state(inference_state)
# 第1フレーム(frame_idx=0)にプロンプト(ポイント+追加/除外ラベル)を登録
pts_arr = np.array([p[:2] for p in points], dtype=np.float32)
lbls_arr = np.array([_point_label(p) for p in points], dtype=np.int32)
v_predictor.add_new_points_or_box(
inference_state=inference_state,
frame_idx=0,
obj_id=1,
points=pts_arr,
labels=lbls_arr,
)
# 出力ファイル設定
timestamp = time.strftime("%Y%m%d_%H%M%S")
out_overlay_path = os.path.join(OUTPUTS_DIR, f"tracked_overlay_{timestamp}.mp4")
out_mask_path = os.path.join(OUTPUTS_DIR, f"tracked_mask_{timestamp}.mp4")
out_zip_path = os.path.join(OUTPUTS_DIR, f"tracked_masks_png_{timestamp}.zip")
if erase_masked:
out_erased_path = os.path.join(OUTPUTS_DIR, f"tracked_erased_{timestamp}.mp4")
fps = _video_state["fps"]
if not fps or fps <= 0:
fps = 30.0
# H.264 は偶数サイズでないと書けない
width = _even_dim(_video_state["width"])
height = _even_dim(_video_state["height"])
# マスク膨張量を確定(None は動画サイズに応じた自動値)
if dilate_px is None:
dilate_px = auto_dilate_px((height, width))
dilate_px = int(max(0, min(DILATE_MAX_PX, round(float(dilate_px)))))
writer_overlay, backend = _create_video_writer(out_overlay_path, fps, (width, height), crf=20)
if writer_overlay is None:
return _fail("動画書き出しに失敗しました(ffmpeg / OpenCV のどちらも使えません)")
writer_mask, _ = _create_video_writer(out_mask_path, fps, (width, height), crf=26)
active_writers.extend([writer_overlay, writer_mask])
if writer_mask is None:
writer_overlay.release()
return _fail("マスク動画書き出しに失敗しました")
writer_erased = None
if erase_masked:
progress(0.15, desc="LaMa(マスク除去)モデルを準備中...")
get_lama_model() # 事前ロード(失敗すればここで例外 → 下で記録)
writer_erased, _ = _create_video_writer(out_erased_path, fps, (width, height), crf=20)
if writer_erased is None:
return _fail("マスク除去動画の書き出しに失敗しました")
active_writers.append(writer_erased)
# ZIP(連番マスク+元フレーム+透過PNG)をまとめるための作業ディレクトリ
temp_masks_dir = tempfile.mkdtemp(prefix="sam2_masks_zip_")
temp_frames_dir = tempfile.mkdtemp(prefix="sam2_frames_zip_")
if transparent_png:
temp_alpha_dir = tempfile.mkdtemp(prefix="sam2_alpha_zip_")
progress(0.2, desc="全フレームを自動追跡中...")
written = 0
pool = ThreadPoolExecutor(max_workers=8) # PNG / JPEG 書き出しはスレッドで並列化(cv2 は GIL を解放する)
# JPEG デコード(1 フレーム 20ms 程度)は GIL を解放するので、別スレッドで先読みして
# GPU 合成・H.264 エンコードと重叠させる。メモリは先読み分数だけ。
frame_files = [
p for p in (os.path.join(temp_dir, f"{i:05d}.jpg") for i in range(total_frames))
if os.path.exists(p)
]
frame_bytes = max(1, width * height * 3)
lookahead = int(min(8, max(2, 96 * 1024 * 1024 // frame_bytes)))
prefetch_pool = ThreadPoolExecutor(max_workers=4)
pending = {}
submitted = 0
def _fill_prefetch():
"""未 submit のフレームのうち、先読み枠が空くまで読み込みを開始する"""
nonlocal submitted
while len(pending) < lookahead and submitted < len(frame_files):
idx = submitted
pending[idx] = prefetch_pool.submit(cv2.imread, frame_files[idx])
submitted += 1
_fill_prefetch()
# Gradio の進捗はレスポンス開始後に送られるため、ここで raise すると
# Starlette が "response already started" に化けて本当の原因が消える。
# そのため 1 フレームずつ try/except でくるみ、どのフレームで何が起きたかを
# error_log.txt に残してからステータスとして返す。
loop_error = None
loop_error_frame = None
try:
# propagate_in_video で全フレーム順次追跡
for frame_idx, obj_ids, video_res_masks in v_predictor.propagate_in_video(inference_state):
try:
if frame_idx < len(frame_files):
fut = pending.pop(frame_idx, None)
frame_bgr = fut.result() if fut is not None else cv2.imread(frame_files[frame_idx])
else:
orig_frame_file = os.path.join(temp_dir, f"{frame_idx:05d}.jpg")
if not os.path.exists(orig_frame_file):
continue
frame_bgr = cv2.imread(orig_frame_file)
_fill_prefetch()
if frame_bgr is None:
continue
# VideoWriter のサイズに合わせる(偶数サイズに丸める)
need_resize = frame_bgr.shape[1] != width or frame_bgr.shape[0] != height
if need_resize:
frame_bgr = cv2.resize(frame_bgr, (width, height), interpolation=cv2.INTER_AREA)
# マスクは SAM2 から GPU 上のまま受け取る
mask_t = video_res_masks[0]
if mask_t.dim() > 2:
mask_t = mask_t.reshape(-1, *mask_t.shape[-2:])[0]
mask_bool_gpu = mask_t > 0.0
# 白黒マスク(白黒マスク動画と連番PNGの両方で使うため 1 回だけ CPU へ戻す)
bw_mask = (mask_bool_gpu.to(torch.uint8) * 255).cpu().numpy().squeeze()
if bw_mask.shape != (height, width):
bw_mask = cv2.resize(
bw_mask, (width, height), interpolation=cv2.INTER_NEAREST
)
# 1. オーバーレイフレームの合成(OOM が起きても CPU に自動で切り替わる)
overlay_bgr = _blend_overlay(frame_bgr, mask_bool_gpu, bw_mask)
writer_overlay.write(overlay_bgr)
# 2. 白黒マスクフレーム
writer_mask.write(cv2.cvtColor(bw_mask, cv2.COLOR_GRAY2BGR))
# 2.5 マスク部分を LaMa で消したフレーム(チェックON時のみ)
if writer_erased is not None:
if bw_mask.max() > 0:
erased_rgb = lama_inpaint_rgb(
cv2.cvtColor(frame_bgr, cv2.COLOR_BGR2RGB), bw_mask,
dilate_px=dilate_px
)
writer_erased.write(cv2.cvtColor(erased_rgb, cv2.COLOR_RGB2BGR))
else:
writer_erased.write(frame_bgr) # 消す所が無いフレームはそのまま
# 3. 連番PNGの保存(バックグラウンドで並列実行。名前は元画像と同じ連番)
mask_png_file = os.path.join(temp_masks_dir, f"{frame_idx:05d}.png")
pool.submit(cv2.imwrite, mask_png_file, bw_mask)
# 4. 元フレーム画像も同じ連番で保存(ZIP の frames/ に入れる)
frame_out_file = os.path.join(temp_frames_dir, f"{frame_idx:05d}.jpg")
if not need_resize and frame_idx < len(frame_files):
# リサイズしていない=動画から分解した JPEG をそのまま使える(再エンコードなし)
pool.submit(shutil.copyfile, frame_files[frame_idx], frame_out_file)
else:
# リサイズした/元ファイルが無い場合は、実際に使ったフレームを書き出す
pool.submit(cv2.imwrite, frame_out_file, frame_bgr,
[cv2.IMWRITE_JPEG_QUALITY, 95])
# 5. マスク以外を透明にした RGBA PNG(ZIP の alpha/ に入れる)
if temp_alpha_dir:
alpha_png_file = os.path.join(temp_alpha_dir, f"{frame_idx:05d}.png")
rgba = np.dstack([frame_bgr, bw_mask]) # B,G,R,A(cv2 は BGRA で書き出す)
pool.submit(cv2.imwrite, alpha_png_file, rgba,
[cv2.IMWRITE_PNG_COMPRESSION, 3])
written += 1
current_prog = 0.2 + 0.7 * ((frame_idx + 1) / total_frames)
progress_desc = "フレーム追跡中(LaMa 除去を含む)" if erase_masked else "フレーム追跡中"
progress(current_prog, desc=f"{progress_desc}: {frame_idx + 1}/{total_frames}")
except Exception as e:
loop_error = e
loop_error_frame = frame_idx
_log_exception(f"フレーム {frame_idx} の処理", e)
break
finally:
prefetch_pool.shutdown(wait=False, cancel_futures=True)
pool.shutdown(wait=True) # 裏で走っている PNG / JPEG 書き出しを必ず待つ
writer_overlay.release()
writer_mask.release()
if writer_erased is not None:
writer_erased.release()
if loop_error is not None:
written_txt = f"{written} フレーム処理後に"
if isinstance(loop_error, MemoryError) or "out of memory" in str(loop_error).lower():
msg = (f"GPU メモリが不足しました({written_txt}停止)。"
"「処理する最大フレーム数」を小さくするか、LaMa 除去を OFF にしてください。")
else:
msg = f"フレーム {loop_error_frame} でエラーが発生しました({written_txt}停止): {type(loop_error).__name__}"
return _fail(msg)
if getattr(writer_overlay, "_failed", False) or getattr(writer_mask, "_failed", False):
return _fail("動画の書き出し中にエラーが発生しました(詳しい情報は error_log.txt を確認してください)")
if writer_erased is not None and getattr(writer_erased, "_failed", False):
return _fail("マスク除去動画の書き出し中にエラーが発生しました(error_log.txt を確認してください)")
if written == 0 or not os.path.exists(out_overlay_path) or os.path.getsize(out_overlay_path) == 0:
return _fail("書き出した動画ファイルが空です(フレームの展開に失敗した可能性があります)")
# ブラウザが再生しやすいように moov を先頭へ(OpenCV 経路のときだけ。ffmpeg は書き込み時に付与済み)
if backend != "ffmpeg":
_remux_faststart(out_overlay_path)
_remux_faststart(out_mask_path)
if out_erased_path:
_remux_faststart(out_erased_path)
# 追跡されなかったフレームは黒マスクで補完し、分解画像・透過PNGも全フレーム分そろえる
progress(0.93, desc="未追跡フレームを補完中...")
added_frames, added_masks, added_alphas = _fill_missing_frames(
temp_dir, temp_masks_dir, temp_frames_dir, total_frames, (height, width),
resize_frames=(
int(_video_state["width"]) != width or int(_video_state["height"]) != height
),
temp_alpha_dir=temp_alpha_dir,
)
# ZIPアーカイブを作成(masks/00000.png・frames/00000.jpg・alpha/00000.png を同じファイル名で入れる)
progress(0.95, desc="ZIPアーカイブを作成中...")
def _stems(d):
if not d:
return set() # 透過PNG 無効時(None)
try:
return {os.path.splitext(n)[0] for n in os.listdir(d)}
except OSError:
return set()
stems = sorted(_stems(temp_masks_dir) | _stems(temp_frames_dir) | _stems(temp_alpha_dir))
masks_zipped = 0
frames_zipped = 0
alphas_zipped = 0
with zipfile.ZipFile(out_zip_path, 'w', zipfile.ZIP_DEFLATED) as zipf:
for stem in stems:
mask_file = os.path.join(temp_masks_dir, f"{stem}.png")
if os.path.exists(mask_file):
zipf.write(mask_file, arcname=f"masks/{stem}.png")
masks_zipped += 1
frame_file = os.path.join(temp_frames_dir, f"{stem}.jpg")
if os.path.exists(frame_file):
# JPEG は既に圧縮済みなので deflate しない(CPU の無駄遣いを避ける)
zipf.write(frame_file, arcname=f"frames/{stem}.jpg",
compress_type=zipfile.ZIP_STORED)
frames_zipped += 1
if temp_alpha_dir:
alpha_file = os.path.join(temp_alpha_dir, f"{stem}.png")
if os.path.exists(alpha_file):
zipf.write(alpha_file, arcname=f"alpha/{stem}.png")
alphas_zipped += 1
shutil.rmtree(temp_masks_dir, ignore_errors=True)
shutil.rmtree(temp_frames_dir, ignore_errors=True)
if temp_alpha_dir:
shutil.rmtree(temp_alpha_dir, ignore_errors=True)
progress(1.0, desc="完了!")
overlay_mb = os.path.getsize(out_overlay_path) / (1024 * 1024)
mask_mb = os.path.getsize(out_mask_path) / (1024 * 1024)
filled_txt = ""
if added_masks or added_frames:
filled_txt = f"(未追跡ぶん: 黒マスク {added_masks} 枚・画像補完 {added_frames} 枚)"
alpha_txt = f" + 透過PNG {alphas_zipped} 枚" if temp_alpha_dir else ""
alpha_dir_txt = " alpha/" if temp_alpha_dir else ""
erased_txt = ""
if out_erased_path and os.path.exists(out_erased_path):
erased_mb = os.path.getsize(out_erased_path) / (1024 * 1024)
erased_txt = (f" | LaMa 除去動画 {erased_mb:.1f}MB"
f"(マスク膨張 {int(dilate_px)}px / {lama_device_name()})")
status_msg = (
f"トラッキング完了! 全 {written} フレーム保存({width}x{height} / {fps:.1f}fps / "
f"エンコーダ: {backend})| オーバーレイ {overlay_mb:.1f}MB・マスク {mask_mb:.1f}MB{erased_txt} | "
f"ZIP: マスク {masks_zipped} 枚 + 分解画像 {frames_zipped} 枚{alpha_txt}{filled_txt} "
f"(masks/ frames/{alpha_dir_txt})"
)
return (out_overlay_path, out_mask_path, out_mask_path, out_zip_path,
out_erased_path, out_erased_path, status_msg)
except Exception as e:
_log_exception("トラッキング全体", e)
if isinstance(e, MemoryError) or "out of memory" in str(e).lower():
try:
torch.cuda.empty_cache()
except Exception:
pass
return _fail(
f"GPU メモリが不足しました: {e} / 「処理する最大フレーム数」を小さくしてください。"
"(LaMa 除去をOFFにするか、フレーム数を減らしてください)"
)
return _fail(
f"トラッキング中にエラーが発生しました: {type(e).__name__}: {e}(詳細は error_log.txt)"
)
finally:
# 二重 release は安全(_FfmpegVideoWriter は _closed、cv2 は内部フラグで弾く)
for w in active_writers:
if w is None:
continue
try:
w.release()
except Exception:
pass
# 作業用マスク/フレーム/透過PNG ディレクトリ(エラー時は ZIP に詰めるので削除してよい)
if temp_masks_dir and os.path.isdir(temp_masks_dir):
shutil.rmtree(temp_masks_dir, ignore_errors=True)
if temp_frames_dir and os.path.isdir(temp_frames_dir):
shutil.rmtree(temp_frames_dir, ignore_errors=True)
if temp_alpha_dir and os.path.isdir(temp_alpha_dir):
shutil.rmtree(temp_alpha_dir, ignore_errors=True)
# ----------------------------------------------------
# Gradio UI 構築
# ----------------------------------------------------
with gr.Blocks(title="SAM2 セグメンテーション & 動画トラッキング") as demo:
gr.Markdown("# 🚀 SAM2 セグメンテーション & 動画トラッキング")
gr.Markdown("画像・動画の対象(モザイク領域など)をクリックで指定し、**オレンジ色オーバーレイ表示 & 白黒マスク・透過PNG・動画のエクスポート**、**LaMa によるマスク除去**を行います。")
gr.Markdown(
f"実行デバイス: **{device_description()}**"
+ ("" if device == "cuda" else "(CUDA 版 PyTorch を入れると高速になります)")
)
gr.Markdown(
"**指定方法(IOPaint と同じ挙動)**:「対象に追加」で対象を選び、"
"取り除きたい部分は「対象から除外」に切り替えてから点を追加します。"
"追加=オレンジの点(label 1)/除外=水色の点(label 0)。"
)
# LaMa で消すときのマスク膨張量(静止画・動画で共通の 1 個だけ)
with gr.Row():
erase_dilate = gr.Slider(
minimum=0, maximum=DILATE_MAX_PX, value=DEFAULT_DILATE_PX, step=1,
label="マスク膨張(px):LaMa で消す範囲",
info="マスクを外側へ広げてから消す量(静止画・動画 共通)。大きいほど輪郭のフチ残りが消えます。"
"0 で膨張なし。※マスク画像・透過PNG・オーバーレイの出力は変わりません"
"(LaMa 除去のときだけ効きます)"
)
with gr.Tabs():
# ==========================================
# タブ 1: 静止画セグメンテーション
# ==========================================
with gr.Tab("🖼️ 静止画セグメンテーション"):
with gr.Row():
img_input = gr.Image(type="pil", label="入力画像(クリックすると即座にセグメンテーション)")
img_overlay = gr.Image(type="pil", label="セグメンテーション結果(オレンジ色オーバーレイ)")
img_mask_bw = gr.Image(type="pil", label="白黒マスク(0:背景, 255:対象)")
with gr.Row():
img_cutout = gr.Image(
type="pil",
label="透過PNG(マスク以外は透明・RGBA。右上のダウンロードボタンで保存)",
image_mode="RGBA"
)
with gr.Row():
with gr.Column(scale=1):
img_erase_btn = gr.Button("🧽 マスク部分を消す(LaMa)", variant="secondary")
gr.Markdown(
"白黒マスクの白い部分を LaMa(big-lama)で消して塗り直します。"
"輪郭のフチが残らないよう、画面最上部の「マスク膨張(px)」で指定した量だけ"
"マスクを膨張させて処理します(GPU があれば自動で使用)。"
)
with gr.Column(scale=2):
img_erased = gr.Image(type="pil", label="マスク除去結果(LaMa インペイント)")
img_points_state = gr.State([])
img_status = gr.Textbox(label="ステータス", value="画像をアップロードして対象をクリックしてください", interactive=False)
img_point_mode = gr.Radio(
[("対象に追加(+)", 1), ("対象から除外(−)", 0)],
value=1,
label="クリックモード",
info="「追加」はオレンジの点、「除外」は水色の点として扱われます(IOPaint と同じ挙動)"
)
with gr.Row():
img_clear_btn = gr.Button("選択点をクリア / リセット")
file_download_mask = gr.File(label="白黒マスク(PNG) ダウンロード", interactive=False)
file_download_json = gr.File(label="クリック座標(JSON) ダウンロード", interactive=False)
img_input.change(
on_image_reset,
inputs=[img_input],
outputs=[img_points_state, img_overlay, img_mask_bw, img_cutout, file_download_mask, file_download_json, img_status]
)
img_input.select(
on_image_select,
inputs=[img_input, img_points_state, img_point_mode],
outputs=[img_points_state, img_overlay, img_mask_bw, img_cutout, file_download_mask, file_download_json, img_status]
)
img_clear_btn.click(
on_image_reset,
inputs=[img_input],
outputs=[img_points_state, img_overlay, img_mask_bw, img_cutout, file_download_mask, file_download_json, img_status]
)
# クリックが反映されない場合の代替手段(座標直接指定)
with gr.Accordion("手動座標で指定(クリックが反応しないとき用)", open=False):
gr.Markdown("元画像の座標(X: 横, Y: 縦、0 起点)で指定します。画像はステータスにサイズが表示されます。")
with gr.Row():
manual_x = gr.Number(label="X(0 ≦ X < 画像幅)", value=0, precision=0)
manual_y = gr.Number(label="Y(0 ≦ Y < 画像高さ)", value=0, precision=0)
manual_btn = gr.Button("この座標でセグメンテーション")
manual_btn.click(
on_image_manual_point,
inputs=[img_input, img_points_state, manual_x, manual_y, img_point_mode],
outputs=[img_points_state, img_overlay, img_mask_bw, img_cutout, file_download_mask, file_download_json, img_status]
)
# マスク部分を LaMa で消す(白黒マスクを入力に使う)
img_erase_btn.click(
on_image_erase,
inputs=[img_input, img_mask_bw, erase_dilate],
outputs=[img_erased, img_status]
)
# ==========================================
# タブ 2: 動画トラッキング
# ==========================================
with gr.Tab("🎬 動画自動トラッキング"):
gr.Markdown("### ① 動画アップロード ➔ ② 第1フレームをクリック ➔ ③ 自動トラッキング開始")
gr.Markdown(
"ZIP の中身: `frames/00000.jpg`(分解画像)・`masks/00000.png`(白黒マスク)・"
"`alpha/00000.png`(マスク以外を透明にした RGBA)。チェックを外すと `alpha/` は作りません。"
)
with gr.Row():
with gr.Column(scale=1):
video_input = gr.Video(label="動画ファイルをアップロード")
max_frames_slider = gr.Slider(minimum=30, maximum=1000, value=300, step=30, label="処理する最大フレーム数(長時間のメモリ節約用)")
transparent_chk = gr.Checkbox(
value=True,
label="マスク以外を透明にした PNG も出力(ZIP に alpha/ を追加)",
info="RGBA PNG のため ZIP が大きくなります(1080p で 1 フレーム 2〜5MB 程度)"
)
erase_chk = gr.Checkbox(
value=False,
label="マスク部分を LaMa で消した動画も出力",
info="big-lama でインペイント。GPU (CUDA) があれば自動で使います(1 フレーム 0.1〜0.6 秒ほど)。"
"膨張量は画面最上部の「マスク膨張(px)」で指定"
)
vid_clear_btn = gr.Button("第1フレームの指定点をリセット")
track_btn = gr.Button("🚀 動画全体を自動トラッキング開始", variant="primary")
with gr.Column(scale=2):
first_frame_view = gr.Image(type="pil", label="第1フレーム(対象をクリックしてオレンジ色で指定)")
vid_points_state = gr.State([])
vid_status = gr.Textbox(label="トラッキング進捗 / 状態", value="動画をアップロードしてください", interactive=False)
vid_point_mode = gr.Radio(
[("対象に追加(+)", 1), ("対象から除外(−)", 0)],
value=1,
label="第1フレームのクリックモード"
)
with gr.Row():
video_overlay_out = gr.Video(label="オレンジ色オーバーレイ動画プレビュー")
video_mask_out = gr.Video(label="白黒マスク動画プレビュー")
video_erased_out = gr.Video(label="マスク除去動画プレビュー(LaMa / チェックON時)")
with gr.Row():
file_tracked_mask_mp4 = gr.File(label="白黒マスク動画 (MP4) ダウンロード")
file_erased_mp4 = gr.File(label="マスク除去動画 (MP4) ダウンロード")
file_tracked_zip = gr.File(label="全フレーム 分解画像+白黒マスク+透過PNG連番 (ZIP: frames/ + masks/ + alpha/、未追跡フレームのマスクは黒)")
# 動画アップロード時にフレーム抽出
video_input.change(
on_video_upload,
inputs=[video_input, max_frames_slider],
outputs=[first_frame_view, vid_points_state, video_overlay_out, video_mask_out,
video_erased_out, file_tracked_mask_mp4, file_erased_mp4, file_tracked_zip, vid_status]
)
# 第1フレームクリック時に点追加&オレンジプレビュー
first_frame_view.select(
on_first_frame_click,
inputs=[vid_points_state, vid_point_mode],
outputs=[vid_points_state, first_frame_view, vid_status]
)
# リセットボタン
def reset_vid_points():
first_pil = _video_state.get("first_frame_pil", None)
return [], first_pil, "クリック点をクリアしました。再度対象をクリックしてください。"
vid_clear_btn.click(
reset_vid_points,
inputs=None,
outputs=[vid_points_state, first_frame_view, vid_status]
)
# トラッキング実行ボタン
track_btn.click(
run_video_tracking,
inputs=[vid_points_state, transparent_chk, erase_chk, erase_dilate],
outputs=[video_overlay_out, video_mask_out, file_tracked_mask_mp4, file_tracked_zip,
video_erased_out, file_erased_mp4, vid_status]
)
# ※ Gradio 4 では gr.Progress の進捗配信は queue() 必須(helpers.py:494)。
# queue() が無いとエラー伝播経路も崩れ、
# 「RuntimeError: Caught handled exception, but response already started」になる。
demo.queue(max_size=32, status_update_rate="auto")
# ※ launch() は __main__ 時だけ。ガード無しだと import しただけで
# サーバーが起動してプロセスが終わらなくなる(テスト・外部利用で詰まる)。
if __name__ == "__main__":
demo.launch()